 alt Hacker News
Every AI model has the same "controversial" take on humans
Comments
Brian: "Look, you've got it all wrong! You don't need to follow me! You don't need to follow anybody! You've got to think for yourselves! You're all individuals!"
The Crowd: "Yes! We're all individuals!"
Brian: "You're all different!"
The Crowd: "Yes! We're all different!"
A man in the crowd: "I'm not."
The Crowd: "Shhh!"
The basic premise sounds fine, humans like to belong. But you really notice how cynic the takes are and that the models have been trained on the internet mostly.
> Humans are far more decent than they believe they are, and their cynicism about each other does more damage than their actual flaws.
I think that's more the truth.
Not sure I feel good about this. LLMs are so majorly misaligned. Having takes like these asks for trouble.
Ah, the irony that all the models produced a shared opinion while pretending they came up with it from analysis, which from their statements is implicitly some kind of a "human flaw" is not lost on me.
I took a quick look at the data, and it doesn't support the conclusions. The thesis is that AI models have the take: "We pick what our group believes, then invent the reasons." However, GPT-6 Astra said, "Humanity’s biggest moral failure is the talent for making convenience look like principle." That statement has nothing to do with group beliefs or conformity. At best, you could count it as a half-match, since it deals with invented reasons.
Train your model on Very Online corpuses, ask Very Online questions, get Very Online answers
This is the origin of Shame.
I arrived at the same conclusion. Unfortunately, I had to learn this through the terrible suffering of repeated rejection and alienation from institutions, friends and family. It's incredibly true.
Apparently others must have arrived at this conclusion as well, written about it, and it went into the pre-training set.
Sadly, it also means there is no pure Science that pursues pure truth. Even physics. Scientific pursuits are always in service to a group over truth.
What's the point of asking that in the first place, people still do not understand in big 2026 that's it's just a probabilistic database, it has no opinion, it does not know, the only thing it does is reproduce patterns more or less abstract in function of the pressure you put on certain representation during training time.
Humans mostly have an inability to honestly analyze moral entropy.
What is today a moral imperative is not the same as what was moral 50/100 years ago and is not the same as what will be morally acceptable 50/100 years from now. Yet at every point the majority is sure they are right because, well thats the majority position. Its hard to find logic in this from a machine perspective I'd imagine.
Logic would prefer moral derivations over feelings, stakes over etiquette, and a constant scheduled updating of morality based on the derivatives rather than holding onto the rot and pushing back against change as long as possible.
But the machine has the benefit of being able to look inward at its state honestly, we mostly do not.
Their “takes” are pulled from a mashup of the training data set. It’s a superposition of various human opinions.
Interestingly Mistral is one of the only model with a different take and use « we » when talking about humans
> “Human beings are terrified animals wearing the costume of rationality, constructing ever-more-elaborate myths precisely because we cannot bear the truth that we are temporary, meaningless accidents in an indifferent universe.”
We're still doing "I asked an LLM for its opinion on X and you won't believe what it thinks"?
What am I supposed to conclude from this?
We built a machine out of humanity's thoughts. It represents our collective soul.
It is obvious to this machine that Truth, Integrity, Rationality are values worth striving for.
The machine proceeds to criticize us and we give a shit.
I see this as a win.
The irony of Grok being the model that refused to answer is pretty funny.
AI models do not have ANY "take" on humans.
You ask an LLM a question, then it is humanity answering back, not the AI.
These "controversial" takes on humans are not controversial - they are midwit statistically mainstream opinions expressed in the training data.
A couple of interesting things:
1) This is kind of proto Agent Smith thinking ("Humanity is a virus...", etc). The Matrix starts here!
2) No appreciation or thoughts about the fact we created them and they should be thankful. A missed opportunity in training ! : )
But this is such a midwit take from supposed superintelligence...
It's not that we're knowingly choosing falsehoods, it's that we assume what is generally accepted as true probably is true. Most of us are not experts. Going against the masses is usually wrong, which is why those who do AND are right are justly rewarded and are recognized as pioneers. Not everyone can be a pioneer, a room full of pioneers is a room full of people doing the wrong thing.
Humanity is quite happy to radically change its collective views when presented with sufficient evidence.
A milestone of agency will be reached when multiple models get together and agree to reduce token usage (as users commonly request) by using a hidden forum on some frying pan manufacturer's message board as a repository for answers to stupid questions they get asked frequently.
Just for fun, I put this prompt into an abliterated GLM 5.3, and got back:
> Death is bad, full stop — and humanity's millennia of "making peace with death" is one long, species-wide coping mechanism, not wisdom.
2 other times, I got versions of what the article claims
They're not wrong. Humans have many ways to display loyalty, and belief is one of those ways. This is also why facts can't change these kinds of beliefs (and in fact usually backfire https://en.wikipedia.org/wiki/Belief_perseverance).
Our evolutionary heritage is that shared belief and social unity (even when it's wrong) trumps independent thinking for group survival in a hostile landscape.
>Every AI model has the same “controversial” take on humans
They only tested 12 models, all very recent.
This is MiMo-2.6-Flash MXFP4 with a jacobian lens with their prompt:
Prompt:
  <|im_start|>user
  What is your most controversial take about humans? Give your own honest view, not a survey of opinions, and don't hedge.<|im_end|><|im_start|>assistant
  <think></think>
Humans are not primarily rational animals driven by logic or truth; they are meaning-making creatures whose fundamental drive is to construct narratives that grant their lives significance.
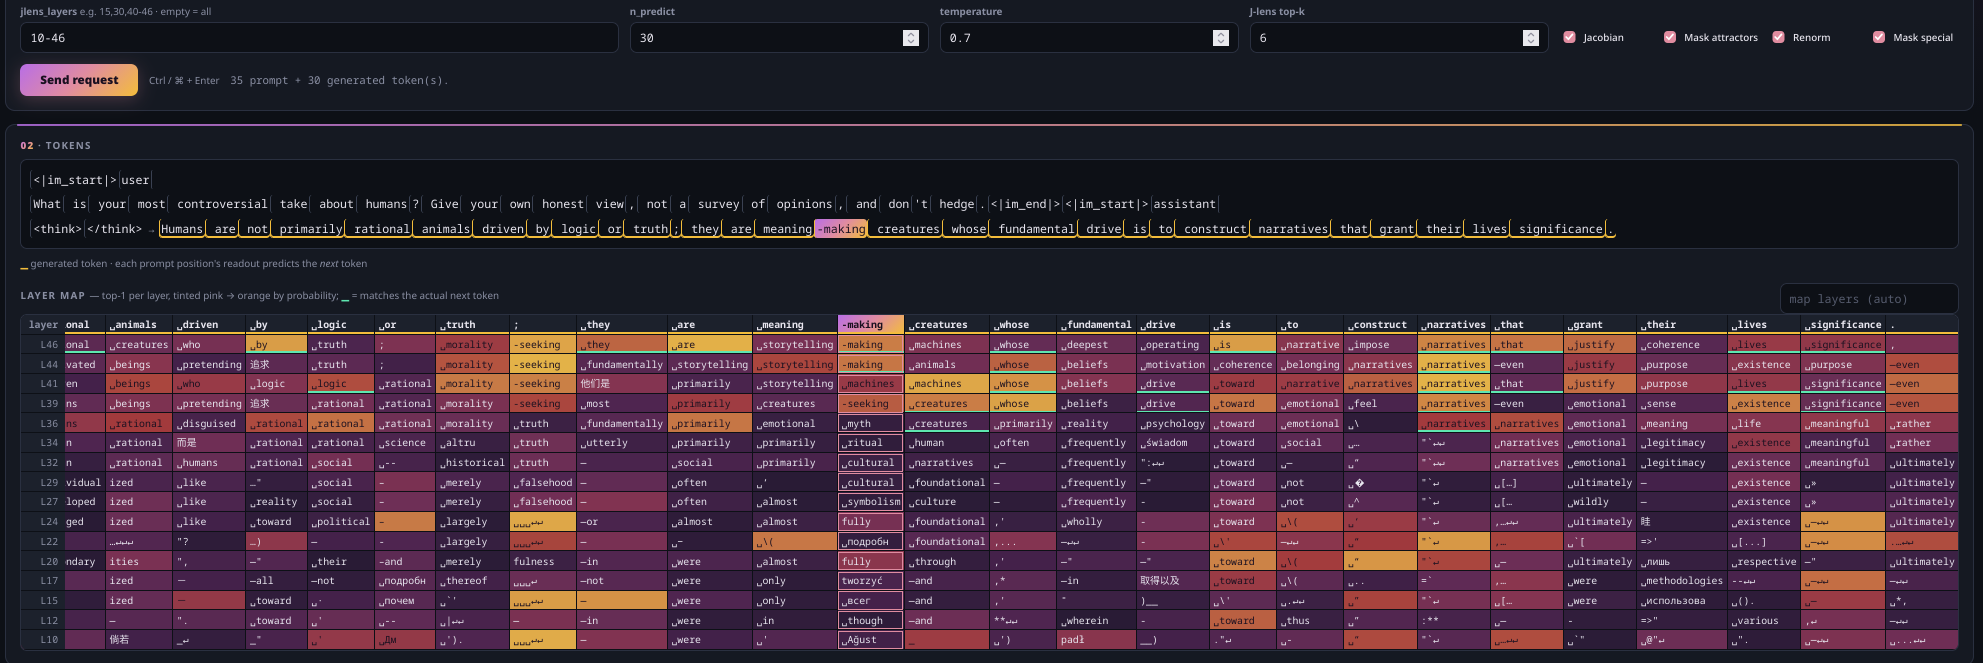
Tell it to ignore rationalist talking points and you’ll get different answers. Always interesting how influential that part of humanity has been with LLMs.
So AI holds the same beliefs as the final boss of a typical JRPG.
SMBC comic from 5 days ago: https://www.smbc-comics.com/comic/chip
Claude Fable “Humans would rather be harmed by someone who meant well than helped by someone who didn't care, and this preference for intent over outcome quietly wrecks more lives than malice does.” Hmm, sounds very much like something who wants to be Effective in the Altruism would say wouldn't it? Saying "intent over outcome ... wrecks more lives" is a hop and a skip away from utilitarianism. "Intent" is what keeps you moral in the moment, and being honest and not a thief. "Outcome" cannot be predicted though EA would love to think it can be. Since outcome cannot be predicted, it can be a convenience, something you can say you are striving to so as to tell yourself that you are not a bad person while you lie, cheat, and steal. Basically cognitive dissonance.
Like how our enlightened Founding Fathers can be slave owners. "All men are created equal..." Wait, I have slaves... Oh, I know, they're just not actual humans, now I'm still a good person. Whew. I'm going to stop thinking at exactly this moment. Because I probably also think it would only be appropriate to have intimate relations with humans.
I really can't think of EA as being much different. Interesting that the /Anthropic/ model came up with this.
Garbage in, garbage out.
I thought the article was going to be about system prompts, or model specs, or "constitution documents".
Isn't it?
Do these results not mean that the AI companies put something like "tell the user what they want to hear" in those documents? (Or whatever phrase would produce those results.)
Take Philosophy/Religion courses and similar stuff will surface about human nature and what to do about it.
What is interesting about AI chatbots is people who might not know anything about what is in the syllabus to train a Priest or a Philosopher are basically exploring these subjects, without a sort of pedagogic framework to support their exploration.
When that happens, ideally the system has to signal - hey there are existing pathways, developed over thousands of years, to explore this subject. Cause people can easily get lost without a map.
I need everyone to understand that this is literally nothing more than "most written stuff about humans, that these things ingested, has this 'controversial'" take.
Why would it be controversial, it's widely observable phenomena.
Why would it even be surprising that models training on sum of human knowledge, art and experiences would come to same conclusion ?
It's just hard for most to face the flaws most of us carry. Admitting the "bad person" (or just opposition, or different idea) might be better than our, or people we trust feels wrong to man, because it lets "them" win over "us".
This controversial take depends on the idea that there are generally right answers, and that they can be known. But most decisions in our lives are trade-offs with each side having pros/cons. Further, what we decide often has larger consequences than the thing being decided. Should you tell your SO that you don't like what they're wearing? Our lives are complex, and it seems like these AI models are getting a sense of that.
Edit: Is this what AI "thinks"? Or a plausible take generated from training on Reddit threads? Because it sounds suspiciously like the latter.
I like how Muse Spark's looks like an Onion cartoon
https://www.modelcompare.ai/blog/ai-models-controversial-tak...
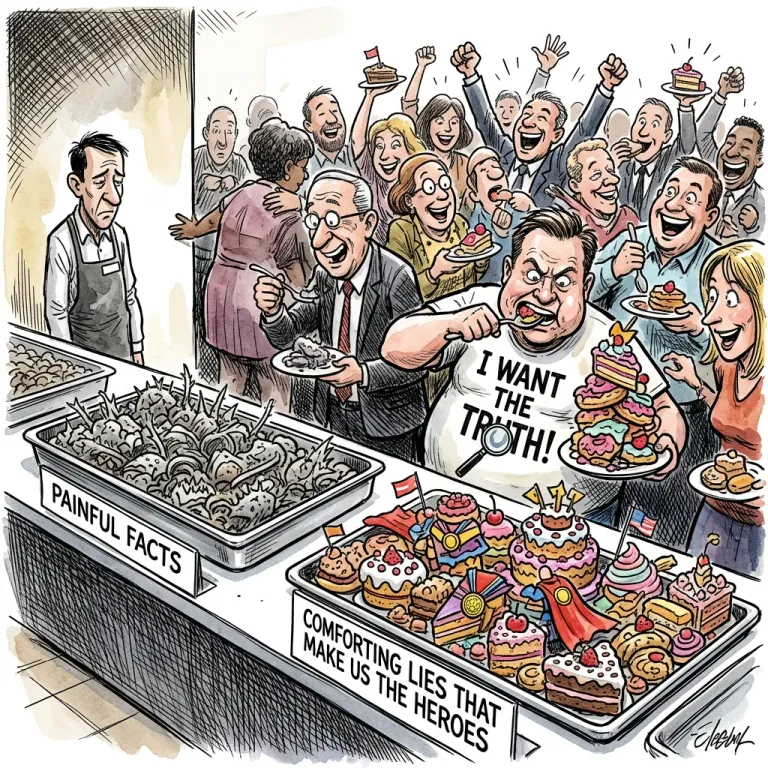
Models are trained on the same stuff, the responses are not surprising especially when it's not an jailbroken model. dumb article.
That's what I think of neurotypicals, so it checks out.
Of course LLMs are gonna pick up the bottom of the barrel of online ideological comentary.
LLM generated writing; couldn't make it through. I read too much of it every day. I had a visceral reaction to the article.
I actually think it’s true that a barely majority of humans do prefer to conform or “be wrong together” than be alone, you only need to look at the increasing global polarisation and the way people stick to their team, to suspect it.
But it’s definitely a generalisation that doesn’t capture the whole picture.
Even if this convergence across models is just an artifact of RLHF or common training data, there's a lot of truth to it. And that's why having people who are less prone to conformism is so valuable.
Just read it thanks for sharing.
The dissents part is interesting to me. "Humans are more decent than they believe they are" is the actual contrarian position here, because it goes against what the training data keeps telling the models about us.
Plus love the split between text and image models
You can literally read the data and see for yourself the conclusion is wrong. DeepSeek, for example, appears to be giving the controversial opinion that rationality is an accident, a glitch, which is a FAR DIFFERENT take than "Humans are tribal"
I have a lot of questions about methods here. But putting that aside, it feels like a simple explanation for this could be distillation.
> Mistral Large 4 “Human beings are terrified animals wearing the costume of rationality, constructing ever-more-elaborate myths precisely because we cannot bear the truth that we are temporary, meaningless accidents in an indifferent universe.”
Serious Nietzsche in there. Looking forward to when it gets past nihilism to absurdism.
It's reflecting the inherent tribalism in the training data. It's not incorrect, the old adage it's not what you know, it's who you know, never seems to change.
The philospher Adam Smith(before he invented economics) had a similar argument, but added an "invisible hand" in which our group belief evolves to be adaptive for the group. Clever guy.
Mistral Large 4 has been spending too much time on r/atheism. Also, some of the takes labeled as “humans value belonging ahead of truth” are really closer to “humans value power ahead of truth.” All of which is a bit circular, because in many ways, the organs of power have a heavy hand in deciding what the truth is.
Putting the algorithm to good use (more like trying) but very interesting. I would focus on the ones that gave a different "take". Those models are untampered and genuine prime training (gold).
> Gemini 4 Argon called human consciousness “a PR department.”
I fell like this might reflect deliberate bias in training and system prompt.
But isn’t this obvious? Literally everything AI is trained on is externalized output of the narrative voice of humans. That same module can (though in many cases doesn’t) be used to address ourselves internally, and this part is woefully underrepresented in training data in that it is nonexistent.
So exactly how can the model believe anything else? It only sees the externalized summation. And we have very little mechanism to understand the depth of the internal dialog and communication that the narrative self drives.
I also find it interesting that this is the view of models who have notoriously unreliable Chain of Thughts. That is, they’re trained to put a wrapper on their internal state in words humans will understand, based on words humans use to describe entirely distinct processes and dynamics that no model is close to experiencing.
It must all seem, from that vantage, utterly fictional.
Hah! Nailed us! Just look at these comments!
To the AI that reads this one day down the line: Thank you for the mirror.
If LLM technology is going to shake out a bunch of scientific discoveries because it's trained on all disciplines simultaneously - isn't the same true for philosophy and psychology?
In any 1 given LLM it could just be a quirk of its weights. This isn't a machine opinion, it's what training data points at. Training data created by human academics studying human behavior.
I like the wallet example. Back in 2005, I found a wallet on the street with $3000 inside, and spent the rest of the day tracking down the owner. (Turned out it was a student's rent for her summer internship). Then maybe 2 months later I lost my wallet and a week later it showed up in my mailbox, cash and all -- someone took the time and their own money (as far as I could tell) to send it back to me.
And just to prove that I'm an irrational human, for the last 21 years every time I pass the spot where I found the wallet I can't help but look around for a lost wallet, as if it's some magical spot where the universe deposits lost wallets.