 alt Hacker News
Claude Fable 5.2 and Mythos 5.2
Comments
I’ve had a chance to use fable 5.2. Some observations:
- Anthropic is finally well balanced across models. Meaning: Opus 5.5 is so good that I do not feel Fable FOMO as I did when it was Fable 5/5.1 vs Opus 4.8/5. And Sonnet 5.5 sometimes makes me forget about Opus.
- Fable is good, but you really have to push the ambition of your prompt in order to see proper separation from Opus 5.5. I personally have a hard time telling the difference between Fable 5.2 and Opus 5.5 for ordinary coding tasks.
- It’s way faster and more reliable: one of the worst things about fable 5.1 was how slow it was an, on top of that, how frequently it would suffer from max output token overflows. I got none of these issues with 5.2.
- Fable is exceptional at drawing. It’s ability to render an image with JavaScript actually has me questioning the value of dedicated image models. I prefer the images I’ve gotten fable/opus to make for me over those from gpt-image, it’s wild to think we’re at this point.
> Starting from an empty folder, the model coordinated over 1,000 subagents, working around the clock for eight days writing, testing, and reviewing code. It produced a working operating system that boots on a laptop
This, to me, shows a problem I have with AI: it is reinforcing inequalities. This is literally brute-forcing an OS by throwing money out the window.
It does not sound AT ALL like a clever way to build an OS. But they can do it because they have orders of magnitudes more money to spend on that than people who would actually know how to build an OS.
The thing is, brute-forcing software may be the best solution to make money. So if you are rich and can brute force software in a dumb way, chances are that you can make a business out of it. If you're poor but know what you are doing, you cannot compete.
Technically, it is impressive that they can get a program to do that, but they are wasting money and energy doing it.
"During prerelease testing they’ve [the models] helped our engineers complete otherwise-infeasible software migrations, designed three working electronic devices from scratch, solved two open problems in the physics of black holes, made substantial progress on robotics evaluations, and formalized the proof of Fermat’s Last Theorem in 30 hours"
Trying to read this with my 2021 brain. Would make me so excited back then. Now I'm not sure what I feel/think about this anymore. One "positive" thing may be I will likely need to get out of the comfy digital shell I've been inhabiting past couple of decades and get some real world skills finally, as those aren't yet replaced by frontier AI.
- Why are they stacking Fable xHigh against Carbon Med?
- How did they produce such a bizarre effort-intel curve for Carbon that goes against every available benchmark?
- Why did they leave Carbon-- positioned primarily as a cyber model-- off of the single cyber benchmark comparison?
- Why do they switch to comparing against Argon (rather than carbon) for robodojo?
We've been early testing Fable 5.2, and have been surprised by its coding ability. It was able to work with an esoteric 600k line fortran codebase to speed up some computational material science work for us by 36 times (!). Given that this could be done in 2 days, we've decided to open-source the results https://github.com/discovered-materials/dm_qe
I'm suprised how bad is marketing and UX on these models. In reality you want a chat app with two send button "Fast" and "Think". I don't want effort x model options (14?)
> Our first formalization of Fermat’s Last Theorem, performed by an unreleased research version of Claude, took 11 days. It relied on a purpose-built harness along with guidance from a human researcher. By contrast, a team of 1,000 Fable 5.2 agents fully formalized the theorem in just 30 hours, with minimal human intervention. Fable 5.2 started from minimal prompts, built its own ways to coordinate, and used no mathematical references, only a list of intermediate theorem statements to score progress. It needed one-third of the action tokens as our first formalization and produced a proof seven times shorter. As can be seen in the figure below, Opus 5.5 (with the same 1,000-agent setup) completed only 26% of the formalization in 18 hours, and barely made any more progress after 30.
Most people don't really have intuitions on what it means to push the frontier now (because AI has surpassed everything they are good at, for example, coding). We are truly inside the singularity (using Kurzweil's definition, slightly paraphrased - the time when technology progresses so fast no one can keep track with it).
Ethan Mollick's take and early testing with Fable 5.2: https://www.oneusefulthing.org/p/fable-52-and-jagged-agi
Just fix the safety classifier. These models are trying to be too brand/PR safe it is getting really annoying.
“Testers have found that Fable 5.2 and Mythos 5.2 communicate more clearly than past Fable and Mythos models. They generate outputs up to 30% faster than Claude Fable 5.1 and Claude Mythos 5.1, and they’re available at a lower price: $8 per million input tokens and $40 per million output tokens.”
Honestly incredible that they’ve managed to beat all benchmarks, while making it cheaper. Always happy to see improvements offered at lower costs.
Will be interesting to see what OpenAI does in response
Why Fable 5.2 and not 5.5?
My hypothesis - OpenAI and Anthropic are locked in battle. Whoever takes a step, the other one mirrors.
Based on this hypothesis, I think we can expect to see a new Astra model soon given the new Fable release.
And it could be that Anthropic released Fable 5.2 and kept 5.5 in reserve, in case the new Astra model performs better than 5.2
I wonder if this is the reason for Opus 5.5 degradation over the last week. Similar things happened to Sonnet when they wanted to push Opus.
As a side note, I think benchmarks need to benchmark on a weekly or daily bases. We saw last week that "Opus 5.5" is just a label with fluctuating performance.
I test models' ability to code by asking them to vibe-code a small game[0]: a Warcraft clone, a Minecraft clone, and a biplane dogfight: https://senko.net/vibecode-bench/
Fable 5.2 doesn't look materially different (if anything, the graphics look worse), but it added more depth to all three games. For example in the warcraft clone, since the goal of the game is to explore 100% of the map and there are lakes, it decided to add an airship unit so the player actually can explore the entire map. Or, since there were guard towers, it decided there should be hostile NPCs otherwise the towers don't make sense.
And in Minecraft case, it decided not to follow Minecraft style too closely (IP infringment guard, perhaps?) so it added a round sun (!!!), two moons (also round :) and a nicer night sky. The rest of the graphics are decidetly worse tho...
[0] not a scientific test, I know; but it gives me an intuition about how a new model behaves, roughly, and it's fun!
There were more than a few "leaks" saying it would be called Fable 5.5, so I'm curious if a) the leaks were just engagementbait or b) Anthropic changed it, despite the fact that Fable 5.2 being better than Opus 5.5 is confusing.
Surprisingly the model is available immediately in my Claude Code: usually there's a delay, either for rollout or safety.
Image to html comparisons of Fable 5.2 and Opus 5.5 (the previous SOTA for this test):
Fable 5.2: https://html.non.io/lcars-fable-5.2/
Opus 5.5: https://html.non.io/lcars-opus-5.5/
Source designs: https://diffui.ai/app/canvas/5093e689-1e74-4f26-b632-2a4500f...
Thoughts:
The best implementation wrt being as true as possible to the source design. It nails the flowing svg shapes. Icons are more accurate to the design - note the difference between the starship svg in the "Legendary platforms" card between Opus 5.5 and Fable 5.2. The 3js planets outside the windows are also really well done, especially the bottom one which has a nice background glow to it.
It isn't without issues though - the flicker effect it added to the S shaped svg that weaves through the page is distracting in my opinion, and I actually thing the motion animation in the Opus 5.5 one is better overall. Still, it nails the implementation of this page, but it's no surprise considering how good Opus 5.5 was at this.
Disclaimer / reminder: the objective of this test isn't to have a well designed webpage, it's a synthetic test that pushes the limits of LLM's vision capabilities. Traditionally LLMs have issues with smooth curves, svg animations, and non-boxy layouts, which this design pushes the limits of.
I tried Fable 5.2 tonight, asking it for a code review of an in-browser machine vision project done by Opus 5.5 over the last 11 days. It used up my 5-hour token budget in half an hour and reported 7 serious bugs; if they're real, they're pretty bad. It's also suggesting that I take a different overall approach to parts of the problem.
But that's just a first impression.
At what point do we really not read code itself anymore? Have Sonnet/Opus write the code, work with the agents on a high level, then have Fable code review and its done.
Any bugs found are looped through agents to fix, and the cycle repeats. Why dig into the code unless for hobby? Just as people don’t write assembly anymore unless for hobby (or learning)
Only exception might be the upper echelons of optimization, like language authors or compiler level work. But even then…
Does this coincide with the claimed nerfing of Opus 5.5? https://news.ycombinator.com/item?id=50422069
Setting aside the comments about nerfing, do normal mortals out there have workflows that really require Fable/Mythos and don't just work fine on Opus 5.5?
I've been using Opus 5.5 on xhigh for some decently aggressive software development on a ~125k-line project, and it has been fine for me. I'm not really willing to dive into a "rewrite the whole project, don't make any mistakes" level of refactoring. I'm not looking to try to prove Fermat's Last Theorem myself. Is there anything that I'm truly missing?
> Claude Mythos 5.2 is our most capable model for cybersecurity engineering. It catches more vulnerabilities than our previous models, and is better at reproducing and fixing them (note that Claude Fable 5.2’s safeguards will block most cybersecurity-related tasks).
Why even rank Fable 5.2's capability in Cybersecurity if you won't allow us to use it for that?
>The model that underlies Claude Fable 5.2 and Claude Mythos 5.2 is a step forward in general capabilities. However, during the model’s training, we took steps to limit advances in the specific research capabilities that could most directly accelerate AI development.
This means that they are blocking the research of AI to different people other than their own?
Looking at Artificial Analysis index, the price is absurd to me.
https://artificialanalysis.ai/
GPT-6.1 Sol costs $1.27 per task, whereas Fable 5.2 is $26.54 per task -- a ~21x price difference.
Fable 5.2 is not 21 times better than GPT 6.1 Sol, I find it hard to justify this.
My experience is that, using Fable to do regular coding or code review work, it's not much better than Opus. But using Fable to do deep thorough audit of the codebase and the system, it's able to catch more problems than Opus can.
We've gotten to the point where you have to be doing some seriously ambitious stuff to see a difference between fable and opus. Both execute beautifully, but I think for my workflows I'll still be using opus 5.5
I'm not impressed. First thing it did was literally destroy the entire codebase when I asked it to fix some bugs.
I'd pay twice as much per token if there was a guarantee they weren't nerfing the model and if it is as good as the original Fable was when it was released. I'm doubtful though. Whatever "tweaks" they've been doing (safety? performance? "saving the best for ourselves") has really taken away the magic for me. I want the LLM magic back.
Pelicans for thinking levels low, medium, high, and xhigh:
https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
max is in there too, but it ran out of reasoning tokens (128,000 limit) before it got to the actual SVG.
Looks like some plans get extra fable usage: https://support.claude.com/en/articles/17506494-claude-fable...
Tested Fable 5.2 for some work tasks, using my automated commit reviewer plugin (https://github.com/rladr-org/reviewer-agent)
gpt-6-luna XHIGH as the reviewer agent still found plenty of bugs that Fable 5.2 missed!
Here was Fable's summary of the session:
The reviewer ran 16 reviews over 9 commits this session (7 rejections, 9 required fixes, all valid); three of them, on the plan, changed how the numbers are computed.(Credit to u/yewenjie for source)> Our first formalization of Fermat’s Last Theorem, performed by an unreleased research version of Claude, took 11 days. It relied on a purpose-built harness along with guidance from a human researcher. By contrast, a team of 1,000 Fable 5.2 agents fully formalized the theorem in just 30 hours, with minimal human intervention. Fable 5.2 started from minimal prompts, built its own ways to coordinate, and used no mathematical references, only a list of intermediate theorem statements to score progress. It needed one-third of the action tokens as our first formalization and produced a proof seven times shorter. As can be seen in the figure below, Opus 5.5 (with the same 1,000-agent setup) completed only 26% of the formalization in 18 hours, and barely made any more progress after 30.
I would imagine Anthropic is hitting a wall on the number of simultaneous agents that can be useful on a task and are working on increasing that maximum. I would assume if they could get twice as much progress by using 10000 simultaneous running fable instances instead, their brief would state that.
IMO, it is very interesting and also very alarming. At some point the barrier to the exponential progress is the amount of computation available. The average human is limited in the number of 'human instances' he or she can interface with at one time.
if 1000 fable instances is better than any human at a task, how about 1 million instances running? Much easier than finding and hiring and coordinating 1000 extremely productive and intelligent human beings. Much cheaper too, it appears.
We are very close to some very scary things happening. I just recently came to terms with the fact that an AI could code and manage coders faster and better than me, I don't think anyones is ready for what is about to happen.
https://www.anthropic.com/research/glm-5-3-and-the-spread-of...
GLM-5.3 almost equal even I've tried it and it is proven for security audit in the blockchain realm
Here's the benchmark: https://playcode.io/blog/macbook-svg-benchmark#compare
If we compare medium or high, then yes, Fable 5.2 is significantly better than Opus 5.5. But it's better not because it's much smarter, but because you can see it's allowed to spend more tokens. At high, Fable 5.2 wrote 76,158 tokens for $3.05. Opus 5.5 wrote 19,767 for $0.40. If you compare by token count, it's just spending more.
The most interesting one was to compare them at max. Streamed, Fable 5.2 spent the whole 128K output ceiling on thinking and returned nothing. Given 300K on the Batch API, it finished at 250,082 tokens. Opus 5.5 Max needed 255,957.
It turns out it's basically the same as Opus 5.5 Max. I don't see much difference. There's a little bit of a difference, but I think Opus 5.5 actually drew slightly better and is twice as cheap: $5.12 against $10.00 at the standard price. If you look closely, the icons are extremely similar. Fable 5.2: https://playcode.io/marketing/assets/static/claude-fable-5-2... Opus 5.5: https://playcode.io/marketing/assets/static/claude-opus-5-5-...
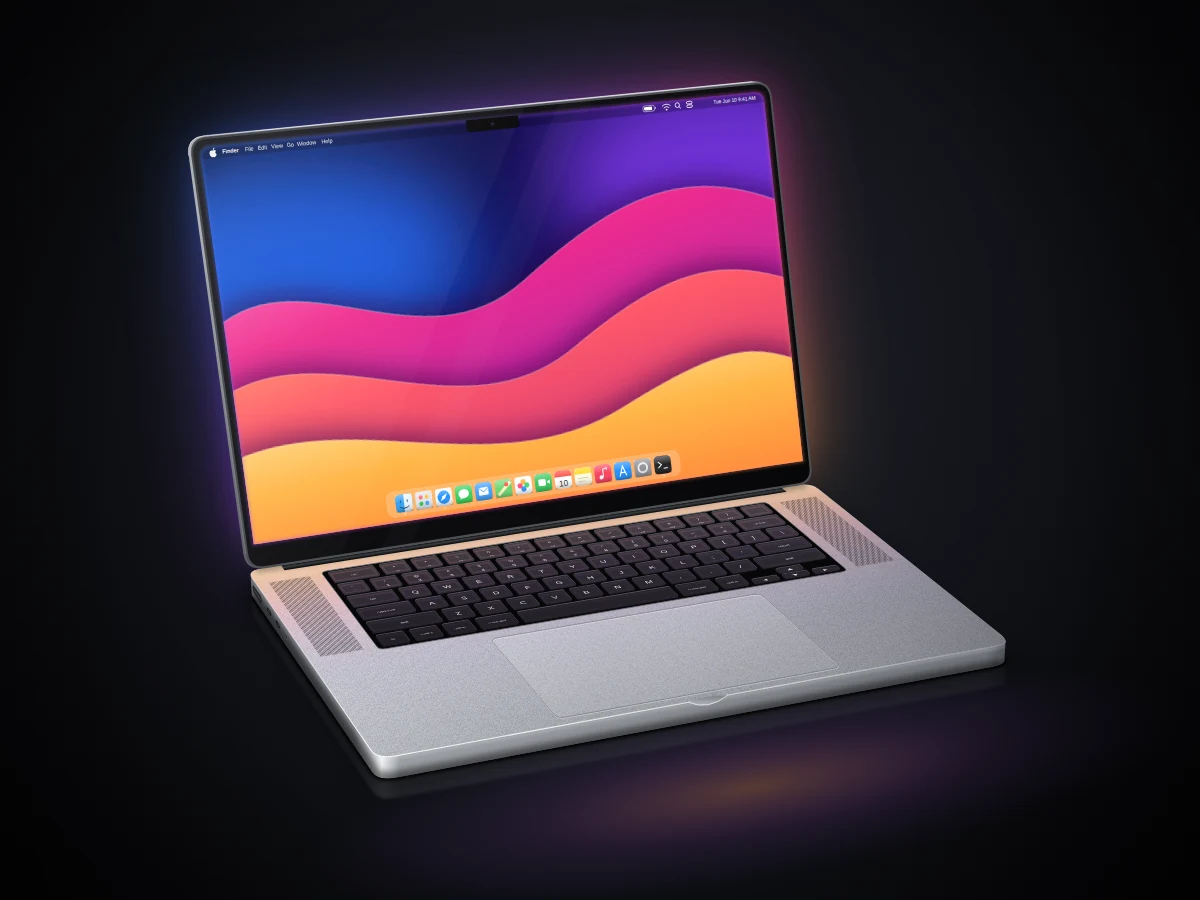
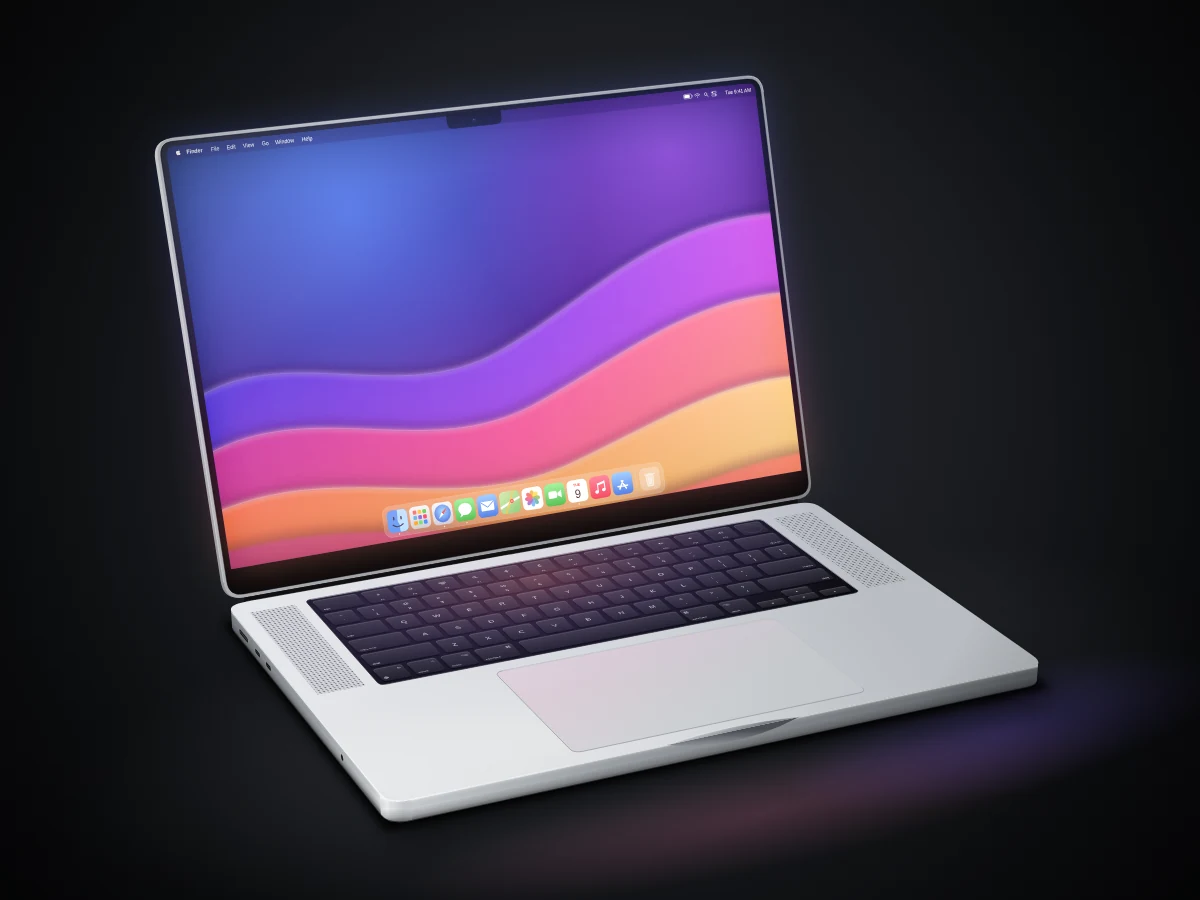
It really looks like they're just tuning the effort level, that's basically it. At different effort levels, they just gave it more context, and the model got smarter.
For now, my recommendation is still to do everything on Opus 5.5 Max. The model won't write that many tokens in agent mode. It only does that when there are no tools at all.
https://www.youtube.com/watch?v=vdYynH177h0
Seems like a new focus is electronics design, which is both interesting and a little sad to me. Manually designing electronics are one of the things I found incredible comfort in doing; seeing AI emerging in this space gives me mixed feelings.
Is this the Model 4 internal name?
Reference: https://x.com/METR_Evals/status/2118412205662314935
I'm very unimpressed after 6 hours of use.
I'm having it rewrite an old system, and it keeps sweeping bugs and incompatibilities in its new implementation, that it knows about, under the rug, seemingly with the hope I won't find them.
Its cheaper at $8 per million input tokens and $40 per million output tokens which is also pretty sweet.
Doubling Remote Labor Index (RLI) - at 41.3% compared to around 20% for the other models - I wonder what kinds of new agentic work this is going to unlock.
Nerfing Opus 5.5 was obvious signal that something new is coming and here we are. I appreciate the resets and lower API price though. Please add selective context compaction, it would probably take an hour max for you to implement it.
Beyond performance, Anthropic has finally (seemingly) nailed a crisp story around its model portfolio.
In my tests Opus 5.5 does better than Fable 5.2, for cheaper.
https://aibenchy.com/compare/anthropic-claude-fable-5-2-high...
I've very interested in the improvements to robotics control capabilities. This model was able to outperform specialized robotics models. It's the bitter lesson coming for robotics.
Every time there's a flagship release like that, I wonder what simple "benchmark task" could I give it to see the the capabilities change in the most obvious way, instead of trusting the official blog post.
I'm not a mathematician to use Erdős problems for testing. I'm also not willing to spend buckloads of tokens just for a test. What is simple and quick but telling? What tasks are not saturated by previous models? Do you have a task you give to all the new models?
Those theoretical physics papers look like the real thing (i.e. not mathematical physics like the OpenAI Yang-Mills result). It looks like AI is finally branching out of math.
This part is mega concerning to me as someone who researches AI for hardware accelerator design and EDA:
  Safeguards

  AI research and development. The model that underlies Claude Fable 5.2 and Claude Mythos 5.2 is a step forward in general capabilities. However, during the model’s training, we took steps to limit advances in the specific research capabilities that could most directly accelerate AI development. Thus, in relevant areas, including accelerator kernel optimization and improving large language model architectures, Fable 5.2 and Claude Mythos 5.2 perform at about the level of Opus 5.5.

  Importantly, we ensured that the training changes did not affect related capabilities like agentic coding, hardware development, and traditional AI or machine learning research (including interpretability research). We do not alter these capabilities as the model is being served to users (that is, at inference time). As described in Section 1.5 of the system card (https://www.anthropic.com/document/claude-fable-5-2-mythos-5-2-system-card) and similarly to previous models, Fable 5.2 and Claude Mythos 5.2 also include transparent fallbacks to Opus 5 for a small set of topics in this domain, including kernel development on certain nonstandard accelerators.
To be clear, they explicitly say they are only targeting very specific capabilities, like accelerator kernel optimization, and that broader hardware development capabilities are unaffected. But 1) even that is pretty bold, especially the part about kernel development for nonstandard accelerator architectures, and 2) I worry that this could eventually expand to more areas of comp. arch., high-level digital design, chip design, and EDA.
My speculation is that, as these kinds of chip design and EDA capabilities become increasingly important to frontier AI labs and their competitive advantages, there will be more incentives to restrict them.
I don't think they've explicitly stated anything like this before regarding restrictions on these specific capabilities, but I could be wrong.
Interestingly, AA[0] reports a 59% hallucination rate on AA-Omniscience, one of the highest among all models and quite a bit higher than even Opus
Why can we say fable 5.2 is better than 5.1 if it needs double the tokens to complete the task? Somehow shouldn't it be compared at same token usage level to see which one is smarter? Why is not the case?
WHo thinks Fable 5.2 is pretty similar to Fable 5.1 when it came out and it's just that 5.1 is so nerfed that a number shift make our perception think it's better.
> As an experiment, one Anthropic engineer gave Fable 5.2 the task of designing a prototype operating system. Starting from an empty folder, the model coordinated over 1,000 subagents, working around the clock for eight days writing, testing, and reviewing code. It produced a working operating system that boots on a laptop, with its own core that runs the machine, drivers for the disk, keyboard, and network, permanent file storage, windows, a login screen, an installer, and built-in Claude functionality (see the video below).
As impressive as this sounds, whether it is tech teams or agent farms, the progress slows down considerably as the codebase grows. The real pain was seldom about shipping v1, but was more about how the v8 scales and how easy it is to get there, how robust the system remains between versions, and how constraints are held.
A huge part of the challenge is to pick/choose the design and implementation strategy that can only come from experience. That is one of the primary reasons why it's an absurd advice to me to let the llm do the goalseek and freestyle. This may be a no big deal on microservice or any managed runtime software that is an update away, but on an embedded or a high availability system where the field upgrade and hardware replacement costs could bankrupt a business.
if llm designed a circuit, will you bankroll it?