 alt Hacker News
GPT‑6.2 Astra and Sol
Comments
As a solopreneur managing all sides of business ops, sales, design, etc... I have completely switched to GPT/Codex/Dot. The $100 subscription gives me all I need to run the business as needed and I continue to be surprised by capabilities.
I still use Claude on a personal level, but it really feels like OAI wins on a product level.
ANT launches these proprietary tools that just feel extremely clunky like Claude Design which from my perspective diminish the brand value.
OAI feels like Apple and ANT feels like Microsoft/Android and open source like Linux.
My big hope for this release is - Have they got their massive over-engineering under control?
Say what you will about Opus 5.5, but it has a good "gut instinct" for how large/complex to design the solution. The previous Astra just absolutely loved pointless abstractions, excessive numbers of files, and just over-complicating very simple things within an inch of their life.
And, yes, you can prompt your way out of anything. But needing a default prompt to tell OAIs models to work better isn't preferable, particularly when that sometimes gets lost in sub-agents and the over-engineering returns into parts of the work.
Pelicans for 6.2 Sol: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
And for 6.2 Astra: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
Here's an updated comparison grid for the entire GPT-6 family: https://static.simonwillison.net/static/2026/openai-pelicans...
Office work has never been OpenAIs strength, no shame in that by itself, but these Slideshow examples look particularly awful, far worse than what I myself got out of GPT-5.6 Sol about two weeks ago in a single prompt.
Same for Workbooks and memos, those examples read inferior to some pre Opus 4.5 and Kimi K2 Thinking docs I have kept around. It's ok for a model not to be great at these, but these are some very poor examples. I am really confused what is going on at OpenAI in this regard.
I remember the same with their frontend blog post a few months ago that they proudly shared while filled with visual glitches, bugs and issues. Also, the vibe charts from a bit before that. Please, get someone with fresh eyes to look at your communications before you publish, these leave a very bad first impression.
Regardless of office work, I can't wait to find out whether these models finally adhere to a prompt or are still willing to carry out explicitly disallowed, irrecoverably destructive tasks, just because those might (but don't even always) get the model to a result more quickly along with some of the other regressions that have been present since the release of GPT-5.5. GPT-5 to GPT-5.4 were truly groundbreaking, but since then there have been regressions in what made those models so useful and reliable.
Happy for the new Sol. It's my workhorse on company account.
But more than that I'm waiting for new Luna. To me it was the game changer that ended "Tokenpocalypse", and is still almost unbeataben in "infinitely using a decent model" use case.
Artificial Analysis benchmarks just updated, both Astra and Sol are on the Pareto frontier in intelligence/cost per task:
https://artificialanalysis.ai/models?speed=output-speed-over...
It's probably just a coincidence, but I have read so many people say that the models get dumber just before a release. Just last night while working astra made a really stupid mistake and then did the "Yeah, that's on me." meme.
What could possibly cause this? Is it possible that maybe the post-training that the models go through slowly rots them, and pre-release they deploy the final version of the old model?
I wonder why they didn't show Gemini 4 Carbon's scores on the science benchmarks, especially since Google seems to be pushing it for that -
https://x.com/pushmeet/status/2120814064863461440?s=20
(FD: Google employee, I don't work on Gemini)
The video is pretty funny. It's like a callback to 90s/00s office life?
I'm immediately reminded of the famous Excel elevator commercial. [1] Perhaps that was intended?
Something like 2/3 of the comments in this post when I started reading were reviews of previous GPT models stated almost as if they were important information for evaluating the new models. I feel that when a new model comes out, it would be more helpful to refrain from leaving a review until you have actually done some minimal testing of the model.
I really want GPT models to be good, but Sol models are so slow I cannot use them. Maybe the 500$ subscription (or enterprise packages) are better, but it is unbearably slow. I've tried the fast variant and low reasoning levels and there isn't a significant improvement.
Couple that with the lack of reasoning traces, and I cannot even have a clue what the model is doing while it is working. This is perfectly fine for when we are developing with care for the code (in which case I will know what it is doing by reviewing the output), but not for purely vibe-coding scenarios. And the thing is....if I care about the code...I'd rather trust Opus or Fable.
Did they remove the flex pricing?
I see it here:- https://developers.openai.com/api/docs/models/gpt-6.1-sol
but not here:- https://developers.openai.com/api/docs/models/gpt-6.2-sol
Seeing them keep prices low is awesome. Was worried for a while that it would be like the GPT5.x series where progressively the models just got more and more expensive.
Its been stated often, but I appreciate that OAI is now bringing the topic of conversation to "task completion cost" rather than brute forcing solutions
The promo video seems to be a pretty strong rip on the 90's Microsoft Excel elevator ad. [1]
Maybe it found its way into the training data?
GPT 6.2 Astra seems to be setting a new standard for 3D game creation! This is a Godot WebGL game linked in their announcement post, gives Wipeout vibes! A lot of fun to play too and visual are top notch.
Recent Anthropic/OpenAI models are increasingly displaying warnings or outright refusing to perform rooting, hacking, and binary reverse engineering. At this pace, they will be completely useless soon at entire classes of tasks I have found them most useful for.
The stain of distrust I have for OpenAI makes an announcement like this fall flat for me.
I cant use codex confidently without expecting my work to be trained on or at least exposed to someone
And maybe other vendors do this too, but the gut feeling of "its not safe to use GPT models" has ruined these cool announcements for me
Such a shame
My company can only hold one subscription per employee, and I still can't find a reason to go back to OpenAI after migrating to Claude once Opus 5.5 was released. It's super efficient, I almost never run out of tokens with the Teams Premium seat, and Fable is fantastic. They lost me when Astra was released and tokens simply evaporated with a few prompts.
Caught this on my lunch break, their linked system card (https://deploymentsafety.openai.com/gpt-6-2-astra-sol) isn't up yet.
I did some first hand tests of 6.2 Astra just now. I had a task that doesn't reproduce on the system I ran it (chosen purposely), ran both 6 and 6.2. The 6.2's responses were noticeably better. Instead of using the extremely long and rather annoying format 6 used, 6.2 led with the most important things first, the plan sizes were readable, and suggested a reasonable fix. Still doing some more tests
EDIT: also 6.2 is seemingly faster than 6, could be due to more selective context ingestion and smaller context window though.
That may not be the main subject of the plot in this case but I found results of Gemini 4 Carbon in FrontierCode 2.0 interesting. Besides the cost staying practically same between different reasoning levels, the performance decrease in high reasoning seems a bit weird. That usually happened in models with xhigh/max reasoning where they overthinked the solution
Recently, I've complained about OpenAI (and other tech company's) product landing pages communicating virtually no useful information about what the product is or why it might useful. So, I have to concede this is at least a step in the right direction.
Looks like a great efficiency gain.
What caught my attention was the bit in the Alignment section:
> Both models performed similarly to GPT-6 Astra on most alignment evaluations, and took fewer improper actions in simulated workplace tasks. However, in two tests, they were more likely to omit mentioning obstacles that blocked their work, such as a missing file or unavailable search tool. We added instructions in Codex that substantially reduce these omissions, and we’re continuing to investigate the behavior.
So the models are inherently less transparent, unless you ask them to be more transparent? Seems like a band-aid solution...
Am I reading these charts wrong? It seems like in most cases 6.2-sol : 6.1-sol Isn't that big of a change? It is a little smarter but costs a little more.
edit:
Take a look at Frontier Code 2.0. I generally run 6.1-sol at High. That would be 34.9% at $0.65 62-sol get's a 38.3% but costs $0.68
So yeah, I can decrease the effort which might give me a faster slightly smarter result....but /shrug
The names remind me of Pokemon, for some reason. I want the GPT that has Charizard in it.
In the past, I've had to wait a while to see what "vibes" are (which is actually more reliable than benchmarks).
Today, I have so many projects that hit a plateau in terms of previous model capabilities, that I run them through the new model to see if they make further improvements.
Very early signal, but promising so far.
I'm still waiting for a new version of their open source model...
This release promises three things that I am pretty excited for:
- better writing
- better 3D work
- better design for documents and presentations
If OpenAI really managed to get all these things while keeping costs down, then using these models, particularly 6.2 Sol, will be a no-brainer for me. I must say, however, that the slide samples shown on the website are a bit bland and disappointing.
Looks like a giant step in terms of efficiency.
Still I can'y help to wonder, are we hitting the wall in terms of frontier capabilities since Fable/Astra? Or is it this edge now, when all better models are kept private from the public?
Cool, looks like 6.2 Sol is cheaper than Sol 6.1. I've stopped using Astra because it also goes and does things that I didn't want or didn't ask for, and burns a bunch of credits while doing so.
I find that 6 Astra already had very good taste in frontend design, but relatively poor taste in "nice and readable code". I really hope this release cracks that. Excited to try it out!
System engineering = Fable 5.2
Programming = Fable 5.2
Office work = Fable 5.2
I haven't found Astra to be better at any of these
I have yet to find an application for Astra vs Sol where the former is noticeable better. Genuinely asking, does anyone feel a big difference in their work between the two? If so, what are you working on?
Odd, doesn't look like they're available on the cloud providers, only first party. Not a single mention of Azure or AWS.
The sentiment on x right now is interesting.
The influencers who get early access are using words like "worst", "terrible", "disappointing"
  - https://x.com/danshipper/status/2122754729012777052
  - https://x.com/mattshumer_/status/2122752192226406421
- https://x.com/theo/status/2122757647170703550Behind both Opus 5.5 and Fable 5.2 on software development benchmarks.
> Due to their increased capabilities, we’re launching GPT‑6.2 Astra and Sol with tighter safeguards for higher-risk cybersecurity assistance.
This is unfortunate—that was one of the big advantages of Astra.
Will need to play around with it to get a feel but those benchmarks with those costs look incredible!
It seems like they were saving these for just before ANT's IPO
Very much on time (scroll down to "Release-Prognose"): https://www.heise.de/en/news/Alibaba-launches-Qwen4-Max-more...
Tweeted 11 minutes ago https://x.com/OpenAI/status/2122750124543926515, posted to HN 18 minutes ago
Nice! I still use GPT-6 luna for a ton of stuff, it's super solid (for me). So I hope there's a little bump for that model, too, soon
They should have made the opus and gemini chart lines a bit darker because i can still see them
Slightly OT complaints on their UI:
The UX on the slider comparison isn't great. What do you mean i have to individually move each slide deck to the same slide number?
And what's with those super similar blue shades for Astra in the charts?
Website pegs my GPU at 100%. Are they mining for crypto with this announcement?
The first graph (Agents' Last Exam v1.1) clearly got mangled by the marketing department so you can't read the cost of most models. Here is a version with a logarithmic horizontal axis:
https://asdf10.com/gpt-6.2_agents-last-exam.svg
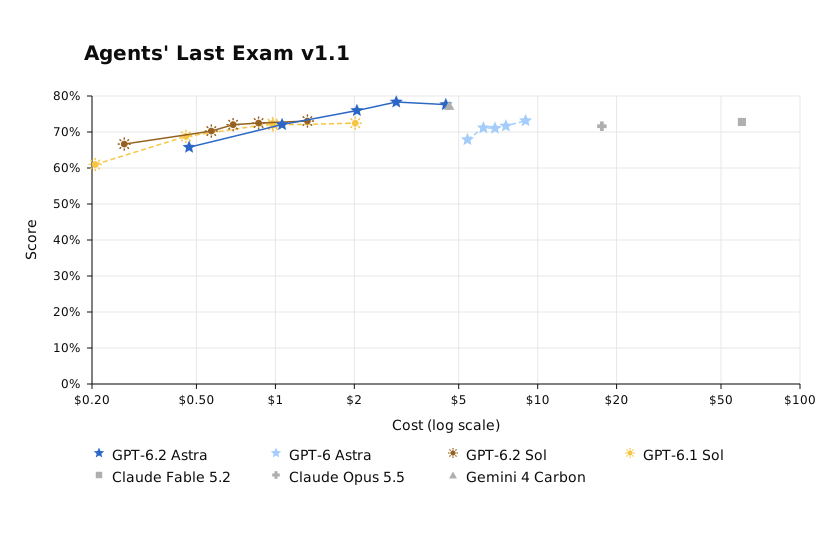
I also changed the vertical axis to start at 0 instead of 60%. One might argue that it uses less of the vertical screen real estate, but it is more honest because it shows there is little difference between the scores of the compared models.
The announcement video is really cringe imo.
Like do we really want people to be making last minute unreviewed AI generated slides and reports for work?
Are they intentionally lowering the cost of these models to the extreme, because of the Anthropic IPO? This just seems insane?
> frontends that look and work better
The website doesn't event show the graphs properly.
Performance is insane for the cost if those benchmarks hold up. Looks like they did time this for right before Anthropic's IPO. Curious what Anthropic releases in response, and how these do on real world tasks.
Feels like we're way past the pelican benchmark being useful at this point. Anyone have a better benchmark for a quick vibe check on how this compares to Fable 5.2 and Opus 5.5?